HTML to Markdown: Clean Output for Tables & Code
Quick answer: HTML to Markdown conversion parses markup into a DOM, discards presentation tags, scripts, styles, and wrapper divs, then maps the remaining semantic elements (headings, links, lists, code blocks, tables, blockquotes) to GitHub Flavored Markdown (GFM). The conversion is lossy by design: structure survives, styling does not.
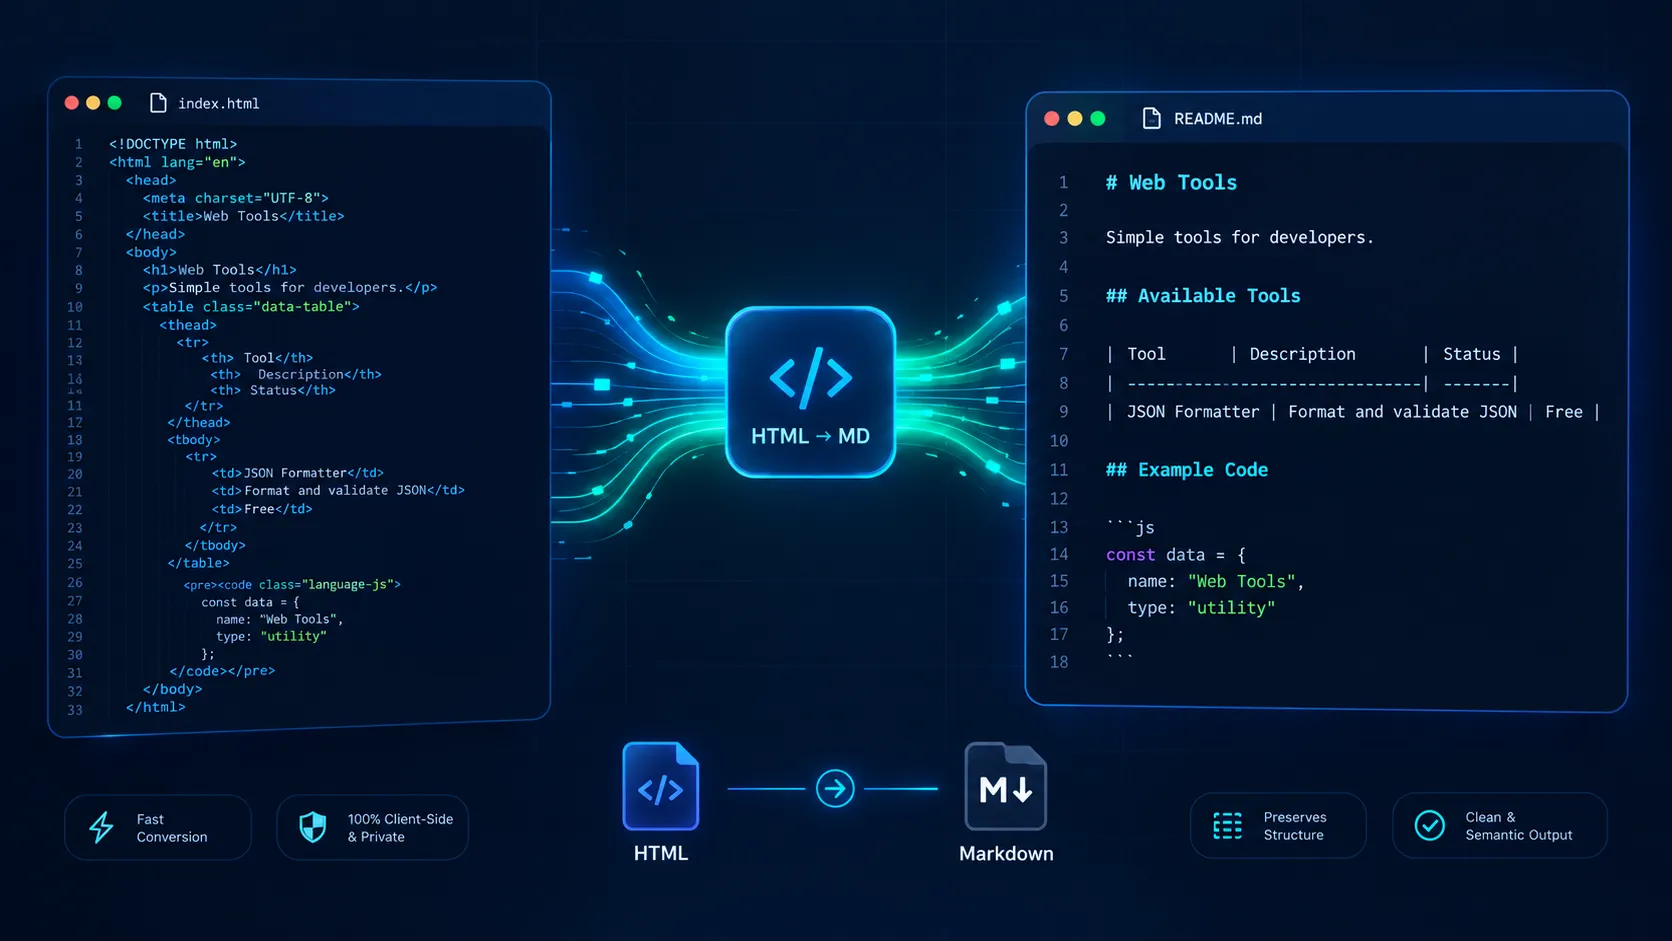
Quick Start
Raw HTML input:
<h2>Quick start</h2><p>Use <a href="/docs">the docs</a>.</p>
Clean Markdown output:
## Quick start
Use the docs.
For a one-off job, paste your markup into the free HTML to Markdown converter. It needs no install and runs entirely in your browser. The rest of this guide covers what conversion drops, how messy markup breaks it, how five tools compare, and a Python script for the reverse direction.
What Does HTML to Markdown Conversion Preserve?
Markdown has roughly a dozen constructs; HTML has over a hundred elements plus a styling language. Anything without a Markdown equivalent gets discarded or flattened, so treat the output as the document's skeleton, not a copy of its appearance.
HTML to Markdown in One Example
This fragment looks like CMS output: wrapper divs, utility classes, an inline style, and a tracking script.
<div class="post-body entry-content" style="max-width:720px">
  <h2 class="title" id="deploy">Deploy checks</h2>
  <p class="lead">Run <code>make verify</code> before merging. Full guide: <a href="/docs/deploy" target="_blank" rel="noopener">deployment docs</a>.</p>
  <ul class="checklist">
    <li><strong>Lint</strong> passes</li>
    <li>Tests <em>green</em></li>
  </ul>
  <div class="grid cols-2"><div class="card"><img src="/img/pipeline.png" alt="Pipeline diagram" width="640"></div></div>
  <blockquote class="note">Rollbacks are manual.</blockquote>
  <script async src="/js/track.js"></script>
</div>
Turndown 7.2.4 with the GFM plugin, with script, style, and noscript removed, produces:
## Deploy checks
Run `make verify` before merging. Full guide: [deployment docs](/docs/deploy).
* **Lint** passes
* Tests _green_

> Rollbacks are manual.
The fixture shrank from 612 characters to 200. Classes, the style attribute, target="_blank", width="640", both wrapper divs, and the script are gone; the heading, link, list, image, and quote remain.
What Survives Conversion—and What Does Not
| Survives (semantic) | Dropped or flattened (presentational) |
|---|---|
Headings <h1> to <h6> |
CSS classes, ids, style attributes |
Links and images (href, src, alt, title) |
Layout: grid, flexbox, floats, wrapper <div> elements |
| Ordered, unordered, and nested lists | <script>, <style>, event-handler attributes |
<pre><code> blocks and inline <code> |
<iframe>, <video>, <audio>, <canvas>, inline SVG |
| Simple tables with one header row | Merged cells (colspan, rowspan), column widths |
| Blockquotes, bold, italic, strikethrough | Colors, fonts, alignment, open/closed state of <details> |
Two losses surprise people: <details> collapses into a run-on string where <summary> fuses with the hidden body, and <video> leaves only its fallback text. Lossy also means one-way; the original layout cannot be rebuilt from the Markdown.
How to Convert HTML to Markdown Online
- Paste an HTML fragment into the input pane, or upload a
.htmlor.htmfile. - The page sanitizes the markup with DOMPurify, then renders GFM.
- Copy the result to the clipboard or download it as a
.mdfile.
To try it on your own markup, convert HTML to Markdown online with a fragment from your CMS. The converter is one page of an all-in-one Markdown conversion workspace (16 dedicated converters), meaning the platform features 16 specialized Markdown converters.
Conversion runs as JavaScript inside your browser tab, and nothing is uploaded to a server. You can check that in under a minute:
- Open the converter, then press F12 (Cmd+Option+I on macOS) and select the Network tab.
- Click the clear icon to empty the request list.
- Paste your HTML and run the conversion.
- Look for new requests. None should carry your markup. Open any entry and inspect its Payload tab.
What Gets Lost in HTML-to-Markdown Conversion?
Presentation Versus Semantic Content
Nested <div> and <span> wrappers carry no Markdown meaning. A correct converter unwraps them and keeps their text:
<div class="wrap"><div class="inner"><span class="lead"><span style="color:#c00">Deploy</span></span> <div><span><b>checks</b></span> run <span class="x">before</span> merge.</div></div></div>
Turndown, markdownify, and html2text all return the same result. The block-level <div> becomes a paragraph break, <b> becomes bold, and the color vanishes:
Deploy

**checks** run before merge.
Pandoc with -t gfm keeps the wrappers as raw HTML. Unwrap them with pandoc -f html-native_divs-native_spans -t gfm-raw_html.
Links, Images, and Code Language Hints
Every library tested passes relative URLs through untouched: href="/docs" becomes [the docs](/docs) and src="img/arch.png" stays as written. That is correct for a fragment with no base URL and wrong the moment the Markdown moves to another domain. Resolve URLs before converting:
from urllib.parse import urljoin
from bs4 import BeautifulSoup

def absolutize(raw_html, base_url):
    soup = BeautifulSoup(raw_html, "html.parser")
    for tag, attr in (("a", "href"), ("img", "src")):
        for el in soup.find_all(tag, **{attr: True}):
            if not el[attr].startswith("#"):  # leave in-page anchors alone
                el[attr] = urljoin(base_url, el[attr])
    return str(soup)
Language hints depend on the <pre><code class="language-python"> convention used by Prism, highlight.js, and most CMS plugins. Turndown and Pandoc read it. markdownify drops it unless you supply a callback:
from markdownify import markdownify

def code_language(pre):
    code = pre.find("code")
    for cls in (code.get("class") or []) if code else []:
        if cls.startswith("language-"):
            return cls[len("language-"):]
    return None

markdown = markdownify(html, heading_style="ATX", code_language_callback=code_language)
html2text emits an indented block with no language at all. Other prefixes such as lang- or highlight- may need a custom rule; these tests used language-.
Malformed CMS and Scraped Markup
Scraped HTML routinely has unclosed tags and crossed nesting. Spec-compliant HTML5 parsers, such as the browser's DOMParser, recover deterministically; lenient legacy parsers do not. This fixture has crossed emphasis, an unclosed paragraph, an unclosed link, and unclosed list items:
<div class="post"><p>First paragraph <b>bold <i>both</b> italic?</i>
<p>Second paragraph with <a href="/x">unclosed link
<ul><li>one<li>two<li>three</ul>
An HTML5 parser (Turndown here) repairs the structure:
First paragraph **bold _both_** _italic?_

Second paragraph with [unclosed link](/x)

*   [one](/x)
*   [two](/x)
*   [three](/x)

[](/x)
The bold and italic nesting is correct. The unclosed <a> was reconstructed into every list item and left an empty link at the end, which is the HTML5 algorithm reconstructing an unclosed formatting element. html5lib builds the same tree. markdownify's default html.parser is worse: the link swallowed the whole list. Parsing with html5lib first fixes that.
HTML Table to Markdown: Handle Colspan and Rowspan
A GFM pipe table has one header row, one delimiter row, and body rows, with exactly one cell per column. The syntax has no way to express a span, so every converter picks its own way to lose that information.
Fixture A has a merged header (<th colspan="2">):
<table>
  <thead>
    <tr><th></th><th colspan="2">Latency (ms)</th></tr>
    <tr><th>Region</th><th>p50</th><th>p99</th></tr>
  </thead>
  <tbody>
    <tr><td>eu-west</td><td>42</td><td>180</td></tr>
    <tr><td>us-east</td><td>35</td><td>150</td></tr>
  </tbody>
</table>
Fixture B has a vertically merged cell (<td rowspan="2">):
<table>
  <thead><tr><th>Region</th><th>Zone</th><th>Latency (ms)</th></tr></thead>
  <tbody>
    <tr><td rowspan="2">us-east</td><td>a</td><td>35</td></tr>
    <tr><td>b</td><td>38</td></tr>
    <tr><td>eu-west</td><td>a</td><td>42</td></tr>
  </tbody>
</table>
Turndown with the GFM plugin turns Fixture A into a header row with two cells, then demotes the real header to a body row with three cells and inserts a second delimiter row:
|  | Latency (ms) |
| --- | --- |
| Region | p50 | p99 |
| --- | --- | --- |
| eu-west | 42 | 180 |
| us-east | 35 | 150 |
You have three practical options:
- Flatten spans and document it: Merge multi-level headers into one row (
Latency (ms) p50,Latency (ms) p99) and note above the table that the original had grouped headers. Best for reference docs. - Duplicate grouped labels across normalized rows: Repeat
us-easton both of its rows so every row stands alone. Best for data that will be sorted, queried, or fed to an LLM. - Keep the raw
<table>block: Use this when layout fidelity is mandatory. Most GFM renderers pass raw HTML tables through.
For options 1 and 2, expand the spans into a plain grid before emitting Markdown:
from bs4 import BeautifulSoup

def expand_spans(table_html):
    """Return (header_rows, body_rows) with every colspan/rowspan expanded."""
    soup = BeautifulSoup(table_html, "html.parser")
    grid, pending = [], {}  # pending: column -> (text, rows still to fill)
    for tr in soup.find_all("tr"):
        cells, row, col = tr.find_all(["td", "th"]), [], 0
        while cells or any(c >= col for c in pending):
            if col in pending:
                text, left = pending.pop(col)
                if left > 1:
                    pending[col] = (text, left - 1)
                row.append(text)
                col += 1
            elif cells:
                cell = cells.pop(0)
                text = cell.get_text(" ", strip=True)
                for _ in range(int(cell.get("colspan", 1))):
                    if int(cell.get("rowspan", 1)) > 1:
                        pending[col] = (text, int(cell["rowspan"]) - 1)
                    row.append(text)
                    col += 1
            else:
                row.append("")
                col += 1
        grid.append(row)
    n_head = len(soup.thead.find_all("tr")) if soup.thead else 1
    return grid[:n_head], grid[n_head:]

def to_gfm(table_html):
    head, body = expand_spans(table_html)
    labels = [" ".join(dict.fromkeys(p for p in col if p)) for col in zip(*head)]
    lines = ["| " + " | ".join(labels) + " |", "|" + " --- |" * len(labels)]
    lines += ["| " + " | ".join(r) + " |" for r in body]
    return "\n".join(lines)
Fixture A comes out with merged headers:
| Region | Latency (ms) p50 | Latency (ms) p99 |
| --- | --- | --- |
| eu-west | 42 | 180 |
| us-east | 35 | 150 |
Fixture B repeats the grouped label on each row:
| Region | Zone | Latency (ms) |
| --- | --- | --- |
| us-east | a | 35 |
| us-east | b | 38 |
| eu-west | a | 42 |
If your table starts as flat data instead of markup, skip HTML entirely. The CSV to Markdown converter, TSV to Markdown converter, and Excel to Markdown converter build pipe tables straight from rows and columns.
HTML-to-Markdown Edge-Case Test Matrix
The matrix compares five methods across six hazards using identical fixtures and default options.
| Hazard | MD Convert (browser) | Turndown JS | markdownify | Pandoc CLI | html2text |
|---|---|---|---|---|---|
Nested <div> / <span> tag soup |
Preserved: wrappers unwrapped | Preserved | Preserved | Repair needed: raw tags kept by default | Preserved |
colspan / rowspan tables |
Repair needed: spans flattened | Fails: stray delimiter row | Fails: cells shift left | Repair needed: valid table, empty cells | Fails: ragged rows |
<pre><code class="language-python"> |
Preserved: language tag kept | Preserved | Repair needed: add callback | Preserved (``` python) | Fails: indented block, no language |
Stripping <script> and <style> |
Preserved: DOMPurify removes them | Repair needed: text leaks unless removed | Preserved | Preserved | Preserved |
| Relative vs. absolute links and images | Repair needed: paths kept as written | Repair needed: paths kept | Repair needed: paths kept | Repair needed: paths kept | Repair needed: paths kept |
| Unclosed tags and broken nesting | Repair needed: HTML5 recovery | Repair needed: link repeated per item | Repair needed: use html5lib |
Repair needed: list correct, emphasis drifts | Fails: crossed tags, dangling brackets |
Which HTML-to-Markdown Method Should You Use?
| Your situation | Batch size | Automation | Privacy need | Pick |
|---|---|---|---|---|
| One page or snippet, private content | 1 to a few | None | High | Browser converter |
| Docs migration, hundreds of files | Large | Nightly or CI job | Medium | Pandoc or markdownify |
| Scraped pages feeding an LLM pipeline | Large | Scheduled | Medium | markdownify (with BeautifulSoup) |
| Sensitive HTML, scripted on own hosts | Any | CI | High | Pandoc or Turndown (no network calls) |
Reduce HTML Token Bloat in LLM and RAG Workflows
Raw HTML spends tokens on tags, attributes, class names, inline styles, URLs, and indentation that a model does not need to understand the content. In CMS fixtures, character count drops by about two thirds. Measure the token savings on your own pages:
# pip install tiktoken markdownify beautifulsoup4
import sys
import tiktoken
from bs4 import BeautifulSoup
from markdownify import markdownify

def html_to_clean_markdown(raw_html):
    soup = BeautifulSoup(raw_html, "html.parser")
    for tag in soup(["script", "style", "noscript", "nav", "footer", "aside", "svg"]):
        tag.decompose()
    root = soup.find("main") or soup.find("article") or soup.body or soup
    return markdownify(str(root), heading_style="ATX")

def count_tokens(text, encoding):
    return len(encoding.encode(text, disallowed_special=()))

if __name__ == "__main__":
    raw_html = open(sys.argv[1], encoding="utf-8").read()
    enc = tiktoken.get_encoding("cl100k_base")
    markdown = html_to_clean_markdown(raw_html)
    before, after = count_tokens(raw_html, enc), count_tokens(markdown, enc)
    print(f"raw HTML : {before:>8,} tokens")
    print(f"Markdown : {after:>8,} tokens")
    print(f"saved    : {1 - after / before:.1%}")
Run it as python token_savings.py page.html. The script strips scripts, styles, navigation, footers, and sidebars first, then converts only <main> or <article>, because boilerplate wastes tokens in either format.
How to Convert Markdown to HTML in Python (Reverse Workflow)
This site converts into Markdown, so the reverse direction is a script you own. markdown_to_html.py imports only sys, re, html, and argparse, installs nothing, and was tested on Python 3.12. It escapes all text with html.escape before adding any tag and neutralizes javascript:, vbscript:, and data: URLs.
#!/usr/bin/env python3
"""markdown_to_html.py - convert a practical Markdown subset to HTML.
Standard library only (sys, re, html, argparse). No pip install.
"""
import argparse
import html
import re
import sys

HEADING_RE = re.compile(r"^ {0,3}(#{1,6})[ \t]+(.+?)(?:[ \t]+#+)?[ \t]*$")
HR_RE = re.compile(r"^ {0,3}([-*_])(?:[ \t]*\1){2,}[ \t]*$")
FENCE_RE = re.compile(r"^ {0,3}(`{3,}|~{3,})[ \t]*([\w+#.-]*)[^\n]*$")
QUOTE_RE = re.compile(r"^ {0,3}>[ ]?(.*)$")
LIST_RE = re.compile(r"^( *)([-*+]|\d{1,9}[.)])[ \t]+(.*)$")

CODE_SPAN_RE = re.compile(r"(`+)(.+?)\1")
ESCAPE_RE = re.compile(r"\\([\\`*_{}\[\]()#+\-.!~|>])")
IMAGE_RE = re.compile(r"!\[([^\]]*)\]\(([^)\s]+)(?:\s+"(.*?)")?\)")
LINK_RE = re.compile(r"\[([^\]]+)\]\(([^)\s]+)(?:\s+"(.*?)")?\)")
STRONG_RES = (
    re.compile(r"\*\*(?=\S)(.+?)(?<=\S)\*\*"),
    re.compile(r"(?<!\w)__(?=\S)(.+?)(?<=\S)__(?!\w)"),
)
EM_RES = (
    re.compile(r"\*(?=\S)(.+?)(?<=\S)\*"),
    re.compile(r"(?<!\w)_(?=\S)(.+?)(?<=\S)_(?!\w)"),
)
UNSAFE_SCHEME_RE = re.compile(r"^(javascript|vbscript|data):")

def safe_url(escaped_url):
    compact = re.sub(r"[\x00-\x20]", "", html.unescape(escaped_url)).lower()
    return "#" if UNSAFE_SCHEME_RE.match(compact) else escaped_url

def emphasis(text):
    for pattern in STRONG_RES:
        text = pattern.sub(r"<strong>\1</strong>", text)
    for pattern in EM_RES:
        text = pattern.sub(r"<em>\1</em>", text)
    return text

def inline(text):
    stash = []
    def keep(fragment):
        stash.append(fragment)
        return "\x00%d\x00" % (len(stash) - 1)

    text = CODE_SPAN_RE.sub(lambda m: keep("<code>%s</code>" % html.escape(m.group(2).strip())), text)
    text = ESCAPE_RE.sub(lambda m: keep(html.escape(m.group(1))), text)
    text = html.escape(text)

    def image(m):
        alt, src, title = m.group(1), safe_url(m.group(2)), m.group(3)
        attr = ' title="%s"' % title if title else ""
        return keep('<img src="%s" alt="%s"%s>' % (src, alt, attr))

    def link(m):
        label, href, title = emphasis(m.group(1)), safe_url(m.group(2)), m.group(3)
        attr = ' title="%s"' % title if title else ""
        return keep('<a href="%s"%s>%s</a>' % (href, attr, label))

    text = IMAGE_RE.sub(image, text)
    text = LINK_RE.sub(link, text)
    text = emphasis(text)
    while "\x00" in text:
        text = re.sub(r"\x00(\d+)\x00", lambda m: stash[int(m.group(1))], text)
    return text

def starts_block(line):
    return bool(HEADING_RE.match(line) or HR_RE.match(line) or FENCE_RE.match(line) or QUOTE_RE.match(line) or LIST_RE.match(line))

def parse_list(lines, i):
    first = LIST_RE.match(lines[i])
    base = len(first.group(1))
    ordered = first.group(2)[0].isdigit()
    items = []
    while i < len(lines):
        line = lines[i]
        if not line.strip():
            j = i
            while j < len(lines) and not lines[j].strip():
                j += 1
            nxt = LIST_RE.match(lines[j]) if j < len(lines) else None
            if nxt and not HR_RE.match(lines[j]) and len(nxt.group(1)) >= base:
                i = j
                continue
            break
        m = LIST_RE.match(line)
        if m and not HR_RE.match(line):
            indent = len(m.group(1))
            if indent < base:
                break
            if indent > base and items:
                nested, i = parse_list(lines, i)
                items[-1]["nested"] += nested
                continue
            if m.group(2)[0].isdigit() != ordered:
                break
            items.append({"text": [m.group(3)], "nested": ""})
            i += 1
        elif items and not starts_block(line) and len(line) - len(line.lstrip()) > base:
            items[-1]["text"].append(line.strip())
            i += 1
        else:
            break

    tag = "ol" if ordered else "ul"
    body = "".join("<li>%s%s</li>\n" % (inline(" ".join(it["text"])), it["nested"]) for it in items)
    return "<%s>\n%s</%s>\n" % (tag, body, tag), i

def blocks(lines):
    out, i, n = [], 0, len(lines)
    while i < n:
        line = lines[i]
        if not line.strip():
            i += 1
            continue
        fence = FENCE_RE.match(line)
        if fence:
            marker, lang = fence.group(1), fence.group(2)
            closer = re.compile(r"^ {0,3}%s{%d,}[ \t]*$" % (re.escape(marker[0]), len(marker)))
            i += 1
            body = []
            while i < n and not closer.match(lines[i]):
                body.append(lines[i])
                i += 1
            i += 1
            cls = ' class="language-%s"' % html.escape(lang) if lang else ""
            code = "".join(l + "\n" for l in body)
            out.append("<pre><code%s>%s</code></pre>" % (cls, html.escape(code)))
            continue
        heading = HEADING_RE.match(line)
        if heading:
            level = len(heading.group(1))
            out.append("<h%d>%s</h%d>" % (level, inline(heading.group(2)), level))
            i += 1
            continue
        if HR_RE.match(line):
            out.append("<hr>")
            i += 1
            continue
        if QUOTE_RE.match(line):
            inner = []
            while i < n and QUOTE_RE.match(lines[i]):
                inner.append(QUOTE_RE.match(lines[i]).group(1))
                i += 1
            out.append("<blockquote>\n%s\n</blockquote>" % "\n".join(blocks(inner)))
            continue
        if LIST_RE.match(line):
            rendered, i = parse_list(lines, i)
            out.append(rendered.rstrip("\n"))
            continue
        para = []
        while i < n and lines[i].strip() and not (para and starts_block(lines[i])):
            para.append(lines[i].lstrip())
            i += 1
        rendered = inline("\n".join(para).strip())
        out.append("<p>%s</p>" % re.sub(r" {2,}\n", "<br>\n", rendered))
    return out

def convert(markdown):
    text = markdown.replace("\r\n", "\n").replace("\r", "\n").replace("\x00", "")
    return "\n".join(blocks(text.expandtabs(4).split("\n"))) + "\n"

def wrap_document(body, title):
    return (
        '<!doctype html>\n<html lang="en">\n<head>\n<meta charset="utf-8">\n'
        '<meta name="viewport" content="width=device-width, initial-scale=1">\n'
        "<title>%s</title>\n</head>\n<body>\n%s</body>\n</html>\n"
        % (html.escape(title), body)
    )

def main(argv=None):
    parser = argparse.ArgumentParser(description="Convert Markdown to HTML using only the Python standard library.")
    parser.add_argument("input", nargs="?", default="-", help="Markdown file; omit or use '-' to read stdin")
    parser.add_argument("-o", "--output", help="write HTML here instead of stdout")
    parser.add_argument("--full", action="store_true", help="wrap the output in a complete HTML5 document")
    parser.add_argument("--title", default="Document", help="<title> used with --full (default: Document)")
    args = parser.parse_args(argv)
    try:
        source = sys.stdin.read() if args.input == "-" else open(args.input, encoding="utf-8").read()
        result = convert(source)
        if args.full:
            result = wrap_document(result, args.title)
        if args.output:
            with open(args.output, "w", encoding="utf-8", newline="\n") as handle:
                handle.write(result)
        else:
            sys.stdout.write(result)
    except OSError as exc:
        print("error: %s" % exc, file=sys.stderr)
        return 1
    return 0

if __name__ == "__main__":
    sys.exit(main())
Privacy and Security: Verify Local Conversion
Sanitization and conversion are separate steps. MD Convert sanitizes the parsed markup with DOMPurify first, removing scripts, event-handler attributes such as onerror and onclick, and script-capable URLs.
Both steps execute as JavaScript in your browser. Your HTML is never uploaded to a server. The site records cookieless aggregate metrics, meaning page-level usage counts, and never the text you paste.
- Network tab: Open DevTools (F12), select Network, clear the list, paste markup, and convert. No request should include your input. Filter by Fetch/XHR and open each entry's Payload tab.
- Offline test: In the Network tab, set throttling to Offline. Paste different markup and convert again. Output still appears, because conversion needs no server.
- Cookie check: Open the Application tab, then Cookies. The site should not have set tracking cookies.
- Metrics request: If a small analytics request appears, open it and confirm it contains counts and page identifiers only, with no fragment of your HTML.
Troubleshooting Broken HTML Conversions
| Symptom | Probable cause | Corrective action |
|---|---|---|
| Table rows have different cell counts, or columns are misaligned | colspan or rowspan in the source; pipe tables allow one cell per column |
Expand spans, then flatten headers or duplicate labels; or keep the raw <table> |
| Images break after publishing the Markdown | Relative src values were kept verbatim and now resolve against a new domain |
Resolve URLs with urljoin before converting |
| Code loses indentation or collapses to one line | A minifier collapsed whitespace inside <pre>, or the code is not wrapped in <pre> |
Re-extract from the unminified source and wrap code in <pre><code> |
| Script or CSS text appears in the output | Turndown keeps script and style text by default; <noscript> fallbacks survive everywhere |
Call remove(['script','style','noscript']), or sanitize first |
Empty [](/url) links, or one link wrapping a whole list |
Unclosed <a> in the source |
Close the tag in the source, or delete matches of \[\]\([^)]*\) |
| Code fences have no language | Source class prefix is not one your converter reads | Use Turndown or Pandoc, or add a markdownify callback |
Frequently Asked Questions (FAQ)
Can HTML tables convert directly to Markdown?
Simple tables can: one header row and one value per cell become a GFM pipe table. Tables with colspan or rowspan cannot convert directly because pipe tables have no span syntax. Flatten the headers, repeat grouped labels on every row, or keep the original <table> as raw HTML.
How do I convert HTML to Markdown in Python?
Install markdownify with pip install markdownify and call markdownify(html, heading_style="ATX"). Pre-parse with BeautifulSoup to drop navigation, pass a code_language_callback to keep code languages, and use html5lib for broken markup. Pandoc, called through subprocess with -t gfm, suits whole documents and batch runs.
Does converting HTML to Markdown reduce LLM tokens?
Usually, because tags, class names, inline styles, and wrapper elements disappear while the text stays. The saving varies by page, so measure it with tiktoken on your own documents. Convert only the main content, since navigation and footers waste tokens in either format.
Is browser-based HTML-to-Markdown conversion private?
When conversion runs client-side, yes. MD Convert executes in your browser with JavaScript, uploads nothing, and records only cookieless aggregate metrics. Verify it yourself: open DevTools, switch to the Network tab, run a conversion, and confirm that no request carries your HTML.
Choose the Right Conversion Workflow
Pick by the job, not by habit:
- One private document, right now: use the browser converter.
- Hundreds of files or CI: script Pandoc or markdownify with the fixes above.
- Tables with merged cells: decide between flatten, duplicate, and raw HTML first, then convert.
- LLM or RAG ingestion: convert main content only and measure tokens.
- Markdown back to HTML: run
markdown_to_html.py.
For a single page or snippet, open the free HTML to Markdown converter, paste your markup, and check the output against the hazards above.